infobro
Writing & Content57Image59Video34Audio & Voice36Chat & Assistants45Productivity65Coding & Development46Agents & Automation36Marketing & SEO26Sales & Support54Business & Finance102Operations21Data & Research31Education27Design27Health & Life38

Ollama vs Together AI

Pricing, features, platforms and who each one suits — side by side.
OOllamaFree · from $16.67/moVisit site
TTogether AIPaidVisit site
VS
O

Choose Ollama if…

  • you want a free plan to start with
  • you want open source you can self-host or audit
  • you work on macOS, Windows, Linux
  • you're in its core audience: developers, ai engineers
T

Choose Together AI if…

  • you work on Web
  • you're in its core audience: ai startups, ml engineers

Side by side

Feature Ollama Together AI
Pricing modelFreemiumPaid
Starting price$16.67/mo—
Free plan
Free trial
API
Open source
Trains AI on your contentNo—
Data retentionCloud prompts/responses processed transiently, not stored beyond request time—
GitHub stars185K—
Works fully offline—
Optional cloud models—
OpenAI-compatible API—
Apple Silicon acceleration—
Runs on CPU only—
Team admin / SSO—
PlatformsmacOS, Windows, Linux, APIWeb, API
CategoryLocal & Open ModelsLLM APIs & Model Hosting
CompanyOllamaTogether AI
Full feature lists

O Ollama

  • Run open models locally with unlimited usage
  • Cloud-hosted open models with pay-as-you-go token pricing
  • Off-peak discounted rates for some models
  • Tool calling support on compatible cloud models
  • Concurrent requests up to 10 on higher plans
  • API keys with per-key cost budgets (Enterprise)
  • Shared team billing and administration
  • Usage alert email at 90% of monthly allowance

T Together AI

  • Serverless pay-per-token inference for open-source models
  • Batch inference up to 30 billion tokens per model
  • Provisioned throughput with 99% uptime SLA
  • Dedicated single-tenant model and container endpoints
  • On-demand and reserved NVIDIA H100, H200, B200, B300 clusters
  • LoRA and full fine-tuning with SFT and DPO
  • Code sandboxes and code interpreter for agents
  • Managed storage with zero egress fees

Their home pages

What each vendor shows first: the pitch, the plans and the sign-up.
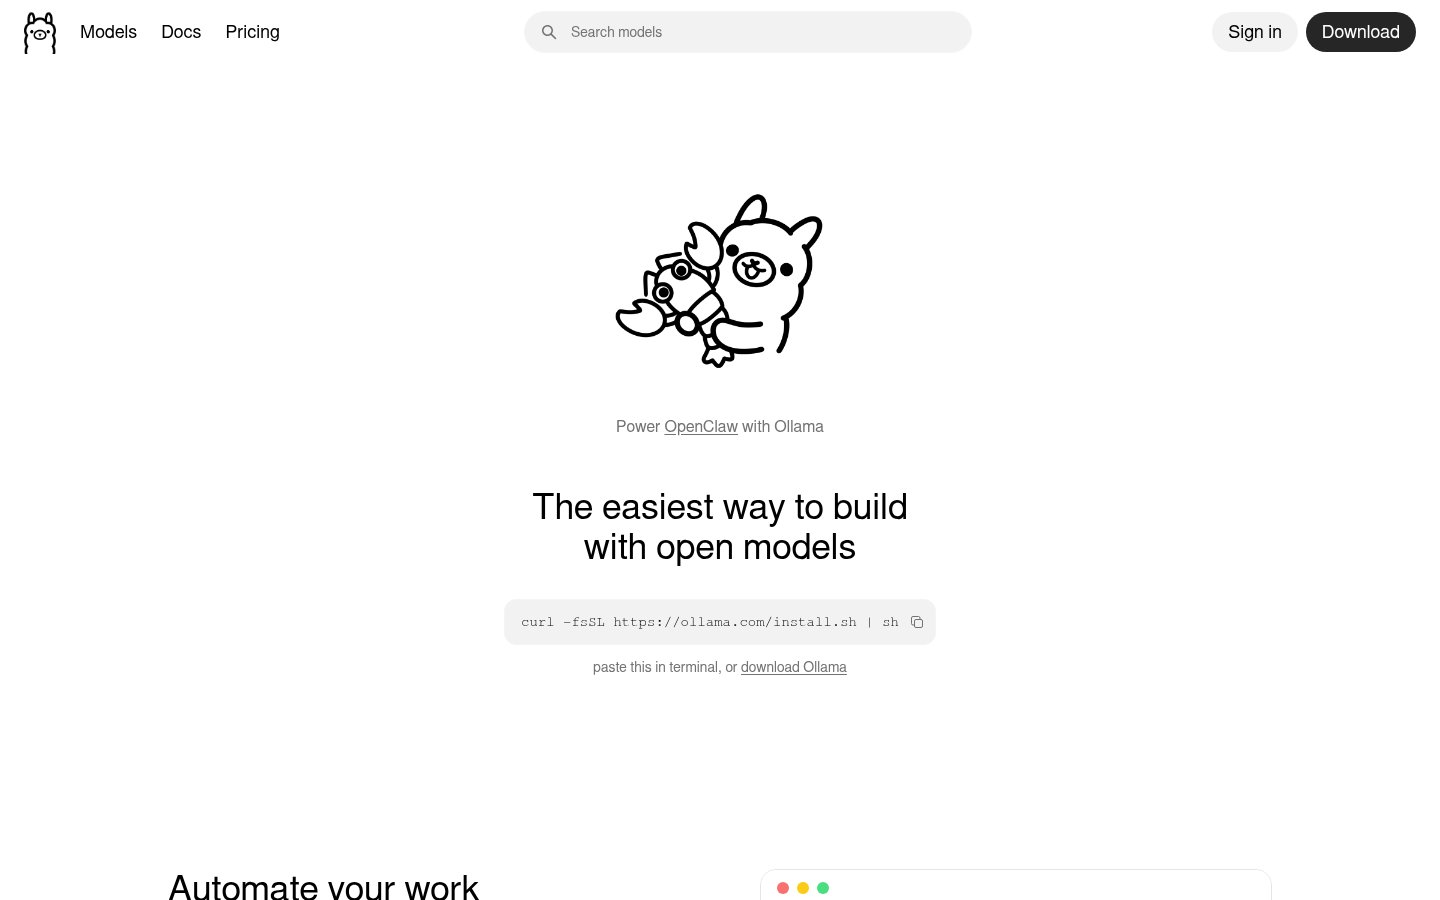
Ollama home page
O Ollama · ollama.ai
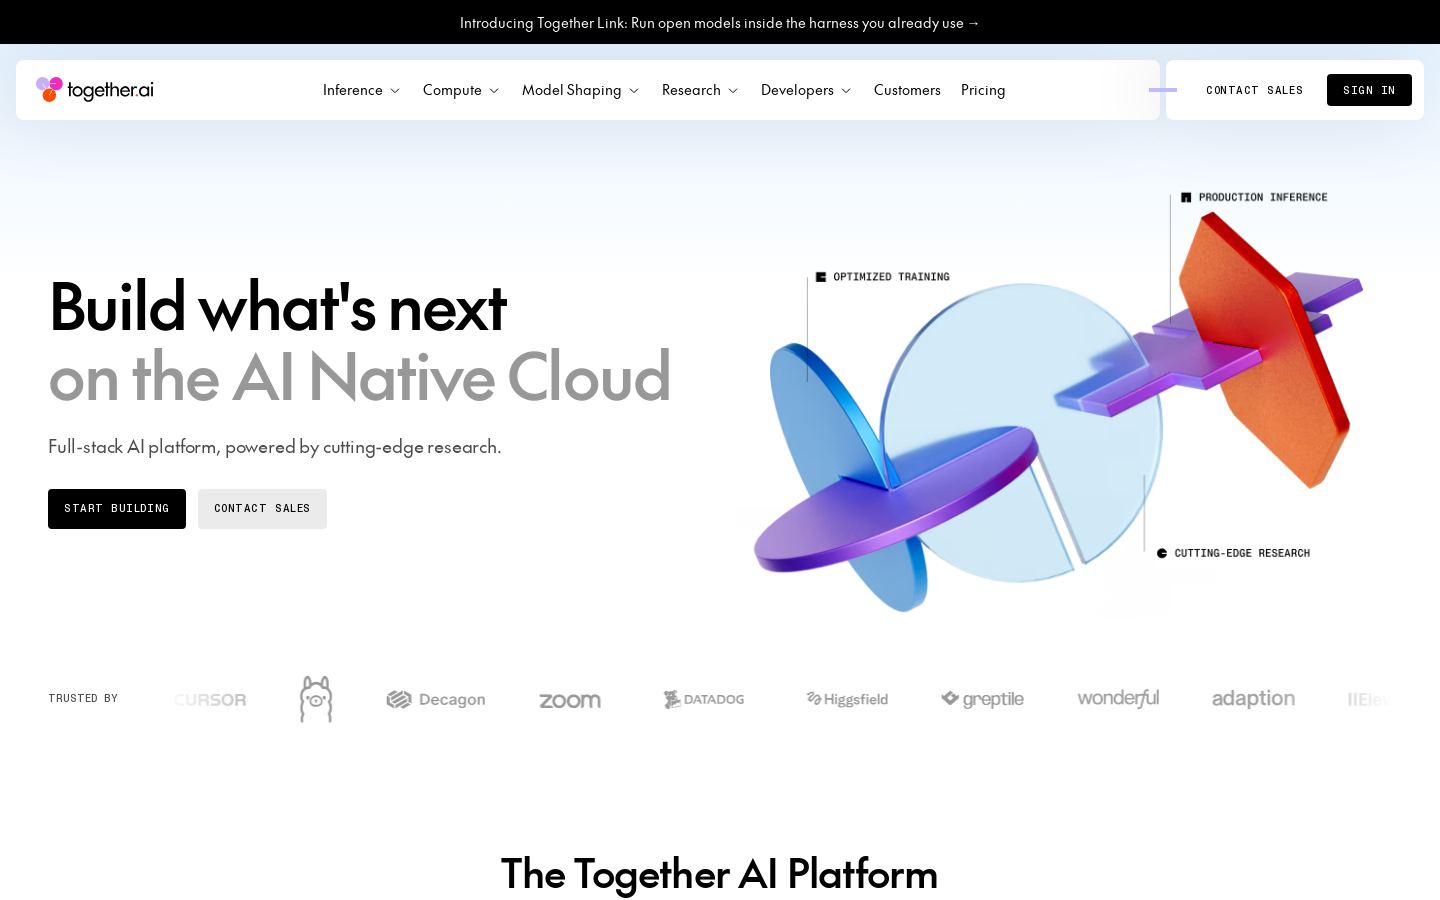
Together AI home page
T Together AI · together.ai

What you'd pay

The cheapest plan that fits, per month, billed yearly where the plan offers it.

Team sizeOllamaTogether AI
1 person$16.67 Prono published plan
5 people$500 Team (early access)no published plan
20 people$500 Team (early access)no published plan

What the free plans include

Ollama

  • Pay as you go: $0 subscription, pay per token for cloud models
  • 3 concurrent requests
  • Running models on your own hardware is unlimited

Together AI

No free plan.

All plans and prices

Ollama

Free$0
Pro$20/mo or $200/yr ($16.67/mo billed annually)
Max$100/mo
Team (early access)$500/mo
EnterpriseCustom

Together AI

Serverless InferenceFrom $0.15 / $0.60 per 1M input/output tokens (gpt-oss-120B)
GPU Clusters (on-demand)$3.99/GPU-hour (H100)
Dedicated Inference$5.49/GPU-hour (H100)
Fine-tuningFrom $0.34 per 1M training tokens (Qwen3.5 9B SFT)
Provisioned ThroughputCustom

Price changes we've recorded

We re-read each pricing page every month and log what changed.

Ollama

No changes since we started tracking.

Together AI

  1. Nov 8, 2026Serverless Inference: $0 → $0.15; New plan: GPU Clusters (on-demand) ($3.99); New plan: Dedicated Inference ($5.49); New plan: Fine-tuning ($0.34); Provisioned Throughput: Per PTU per minute → Custom; Plan dropped: Dedicated Inference (On-demand); Plan dropped: Dedicated Inference (Reserved)

Strengths and limitations

Ollama

  • Local model use is free and unlimited
  • Prompt and response data is never logged or trained on
  • Open source project on GitHub
  • Published per-token prices for every cloud model
  • Free cloud usage is limited to starter models unless you buy credits
  • Unused monthly credits do not roll over
  • Free plan allows only 1 concurrent cloud request
  • Cloud hosting is primarily in the US

Together AI

  • Large catalog of open-source models across text, image, audio and video
  • Published per-token and per-GPU-hour prices
  • Path from serverless to dedicated and reserved capacity
  • Managed storage has no egress fees
  • Reserved GPU and dedicated capacity require contacting sales
  • Fine-tuning jobs carry minimum charges (e.g. $4–$60)
  • Usage-based billing makes monthly costs harder to predict

More comparisons

Other options to consider

L
LM Studio websiteL

Desktop agent for documents, code and automation using local or open models
Free, from $20/mo
L
LM Studio website
Free, from $20/mo
L

Desktop agent for documents, code and automation using local or open models
Local & Open ModelsFree planAPI
G
GPT4All websiteG

Desktop app for running open-source language models locally and privately
Free, from $20/mo
G
GPT4All website
Free, from $20/mo
G

Desktop app for running open-source language models locally and privately
Local & Open ModelsFree plan
R
Replicate websiteR

Run, fine-tune and deploy open-source ML models through a cloud API
Paid
R
Replicate website
Paid
R

Run, fine-tune and deploy open-source ML models through a cloud API
Developer Tools & APIsAPI
M
Mistral websiteM

Open-weight AI models, chat and coding agent you can run on your own infrastructure
Free, from $14.99/mo
M
Mistral website
Free, from $14.99/mo
M

Open-weight AI models, chat and coding agent you can run on your own infrastructure
Local & Open ModelsFree planAPIOpen source
D
DeepSeek websiteD

AI chat assistant and low-cost LLM API for consumers and developers

Freemium
D
DeepSeek website
Freemium
D

AI chat assistant and low-cost LLM API for consumers and developers

AI ChatbotsFree planAPI
F
Fireworks AI websiteF

Inference and fine-tuning platform for open AI models, for developers and teams

From $8/mo
F
Fireworks AI website
From $8/mo
F

Inference and fine-tuning platform for open AI models, for developers and teams

LLM APIs & Model HostingAPI

Facts from each vendor's public pages, prices checked Oct 26, 2026. Editorial policy